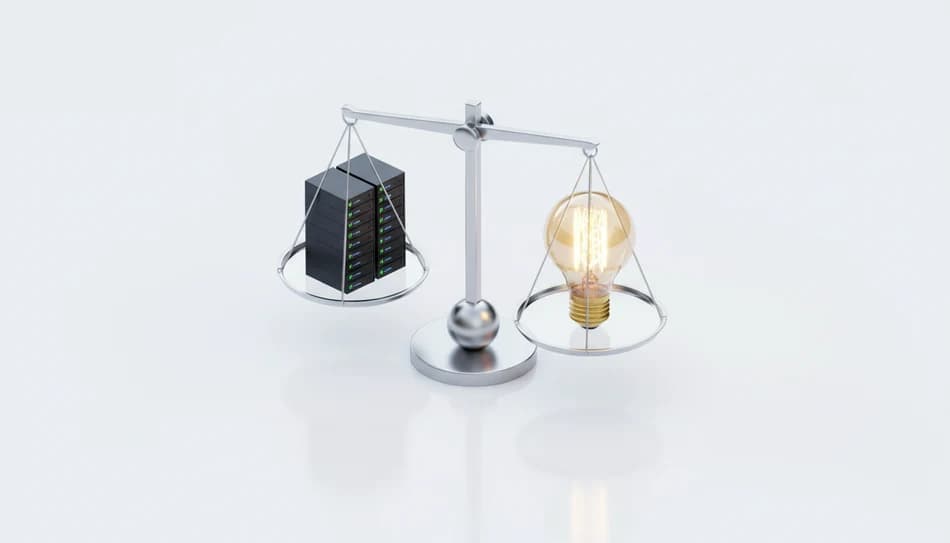
The first AI bill is small and easy to ignore. The tenth arrives after a successful launch and is suddenly the largest line in the infrastructure budget. The fix is rarely a cheaper model — it is knowing where the tokens go.
Where the money actually goes
- Long system prompts resent on every request.
- The same question answered again because nothing is cached.
- A large model doing a job a small one, or a rules engine, could do.
Habits that keep it predictable
Attribute cost to features, cache what repeats, route easy requests to smaller models, and set a budget alert per feature rather than per account. Each of these is a few days of work, and together they usually cut the bill by half.
Topics
- AI costs
- Caching
- Startups
Written by

Alexander Bessudnov
KODEERA
Share